오픈AI
소개
Logfire는 OpenAI에 대한 호출을 감지하기 위해 추가 코드 라인 사용을 지원합니다.
import openai
import logfire

client = openai.Client()

logfire.configure()
logfire.instrument_openai(client)  # (1)!

response = client.chat.completions.create(
    model='gpt-4',
    messages=[
        {'role': 'system', 'content': 'You are a helpful assistant.'},
        {'role': 'user', 'content': 'Please write me a limerick about Python logging.'},
    ],
)
print(response.choices[0].message)
-
클라이언트 측 인스턴스에 액세스할 수 없는 경우 클래스(예:
logfire.instrument_openai(openai.Client))를 통과하거나 인수(즉,logfire.instrument_openai())를 전달하여openai。客户端및openai。AsyncClient클래스를 탐지할 수 있습니다.
_
자세한 내용은 [instrument_openai() API 참조] [logfire. logfire. ity_openai]를 참조하십시오. _
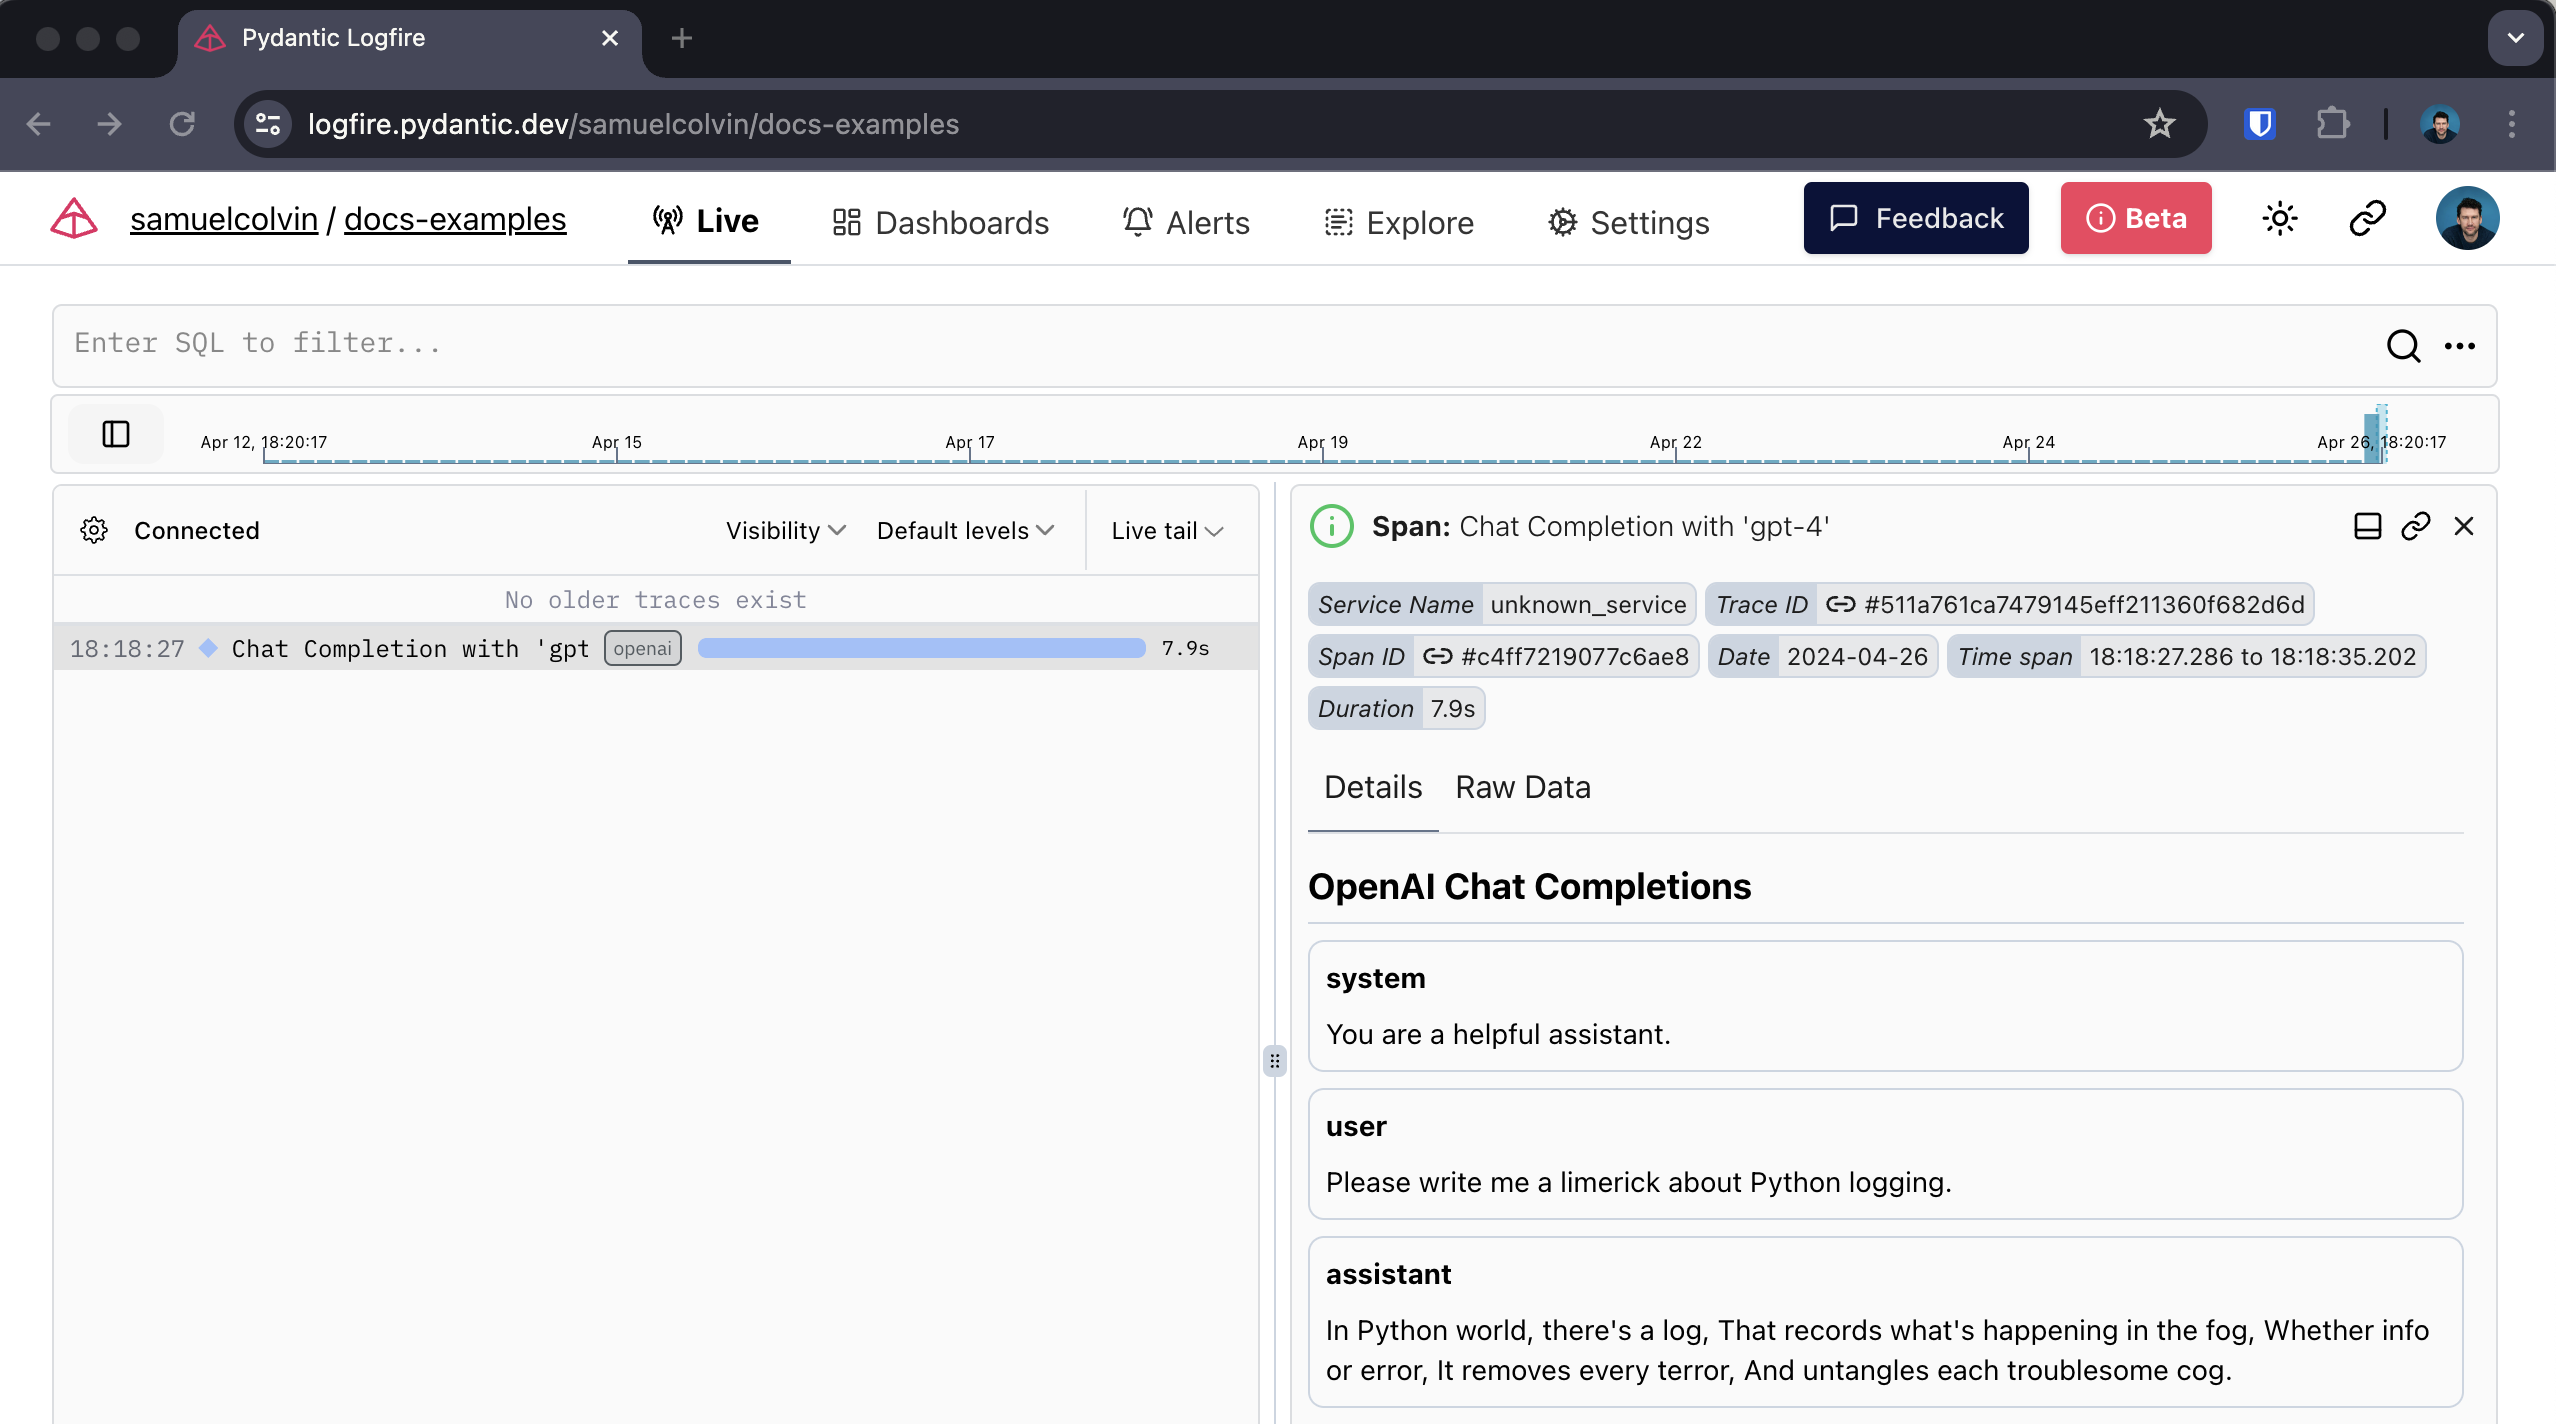
이를 통해 다음을 얻을 수 있습니다.
-
OpenAI에 대한 호출을 둘러싼 범위로, 기간을 기록하고 발생할 수 있는 예외를 포착합니다.
-
사람이 읽을 수 있는 에이전트와의 대화 표시
-
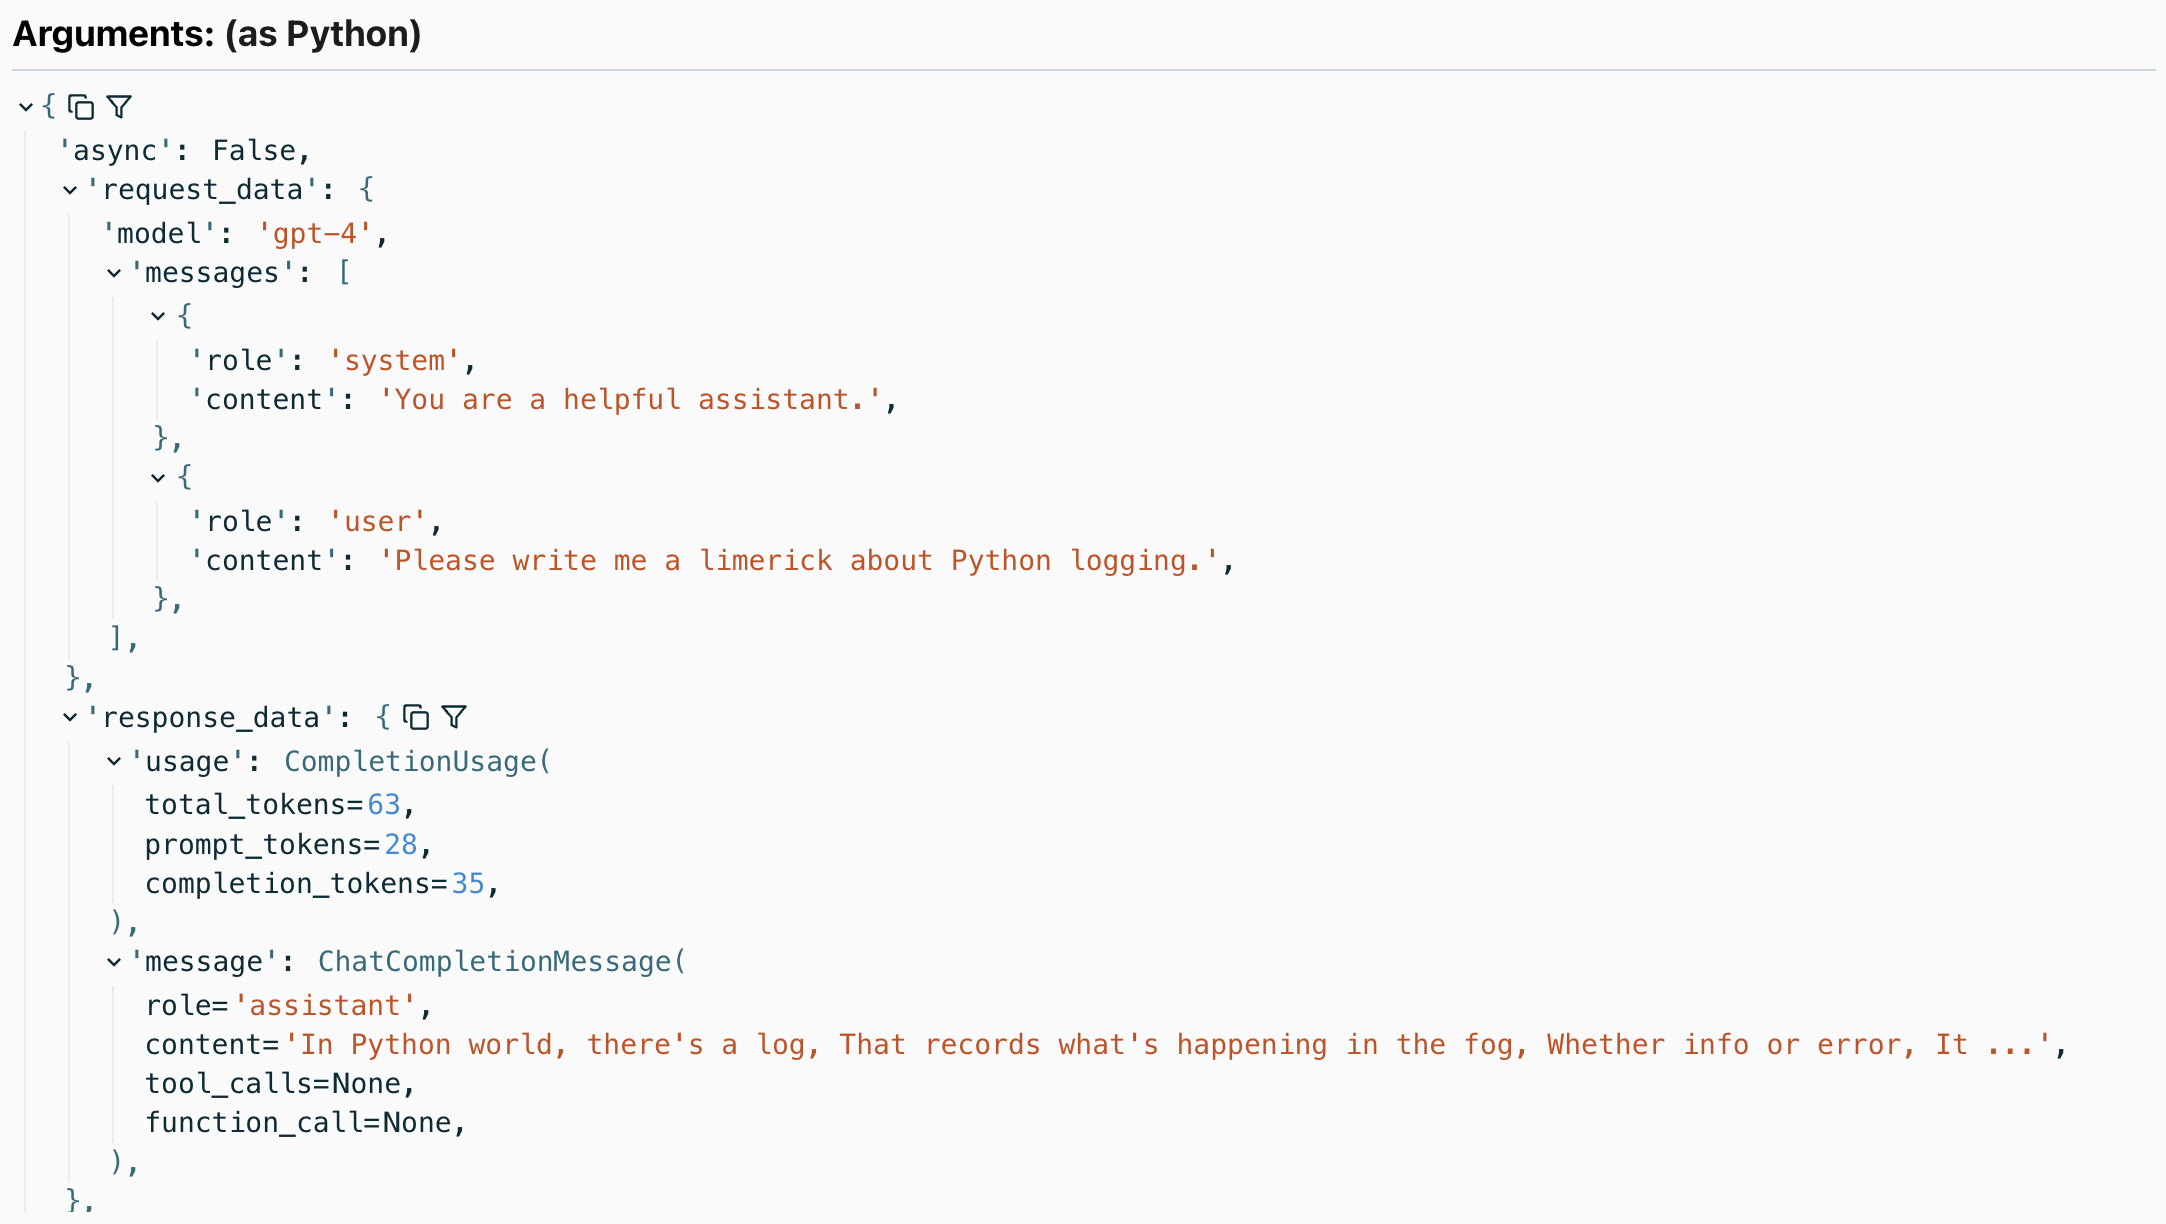
사용된 토큰 수를 포함하여 응답에 대한 세부 정보입니다.
적용되는 방법
다음 OpenAI 방법이 적용됩니다.
-
client.chat.completions.create예 및 아니오.stream=True -
client.completions.create예 및 아니오.stream=True client.embeddings.createclient.images.generate
모든 방법은 openai 中。客户端 및 openai。AsyncClient 에 포함되어 있습니다.
예를 들어, 다음은 이미지 생성 호출의 감지입니다.
import openai
import logfire

async def main():
    client = openai.AsyncClient()
    logfire.configure()
    logfire.instrument_openai(client)

    response = await client.images.generate(
        prompt='Image of R2D2 running through a desert in the style of cyberpunk.',
        model='dall-e-3',
    )
    url = response.data[0].url
    import webbrowser
    webbrowser.open(url)

if __name__ == '__main__':
    import asyncio
    asyncio.run(main())
제공:
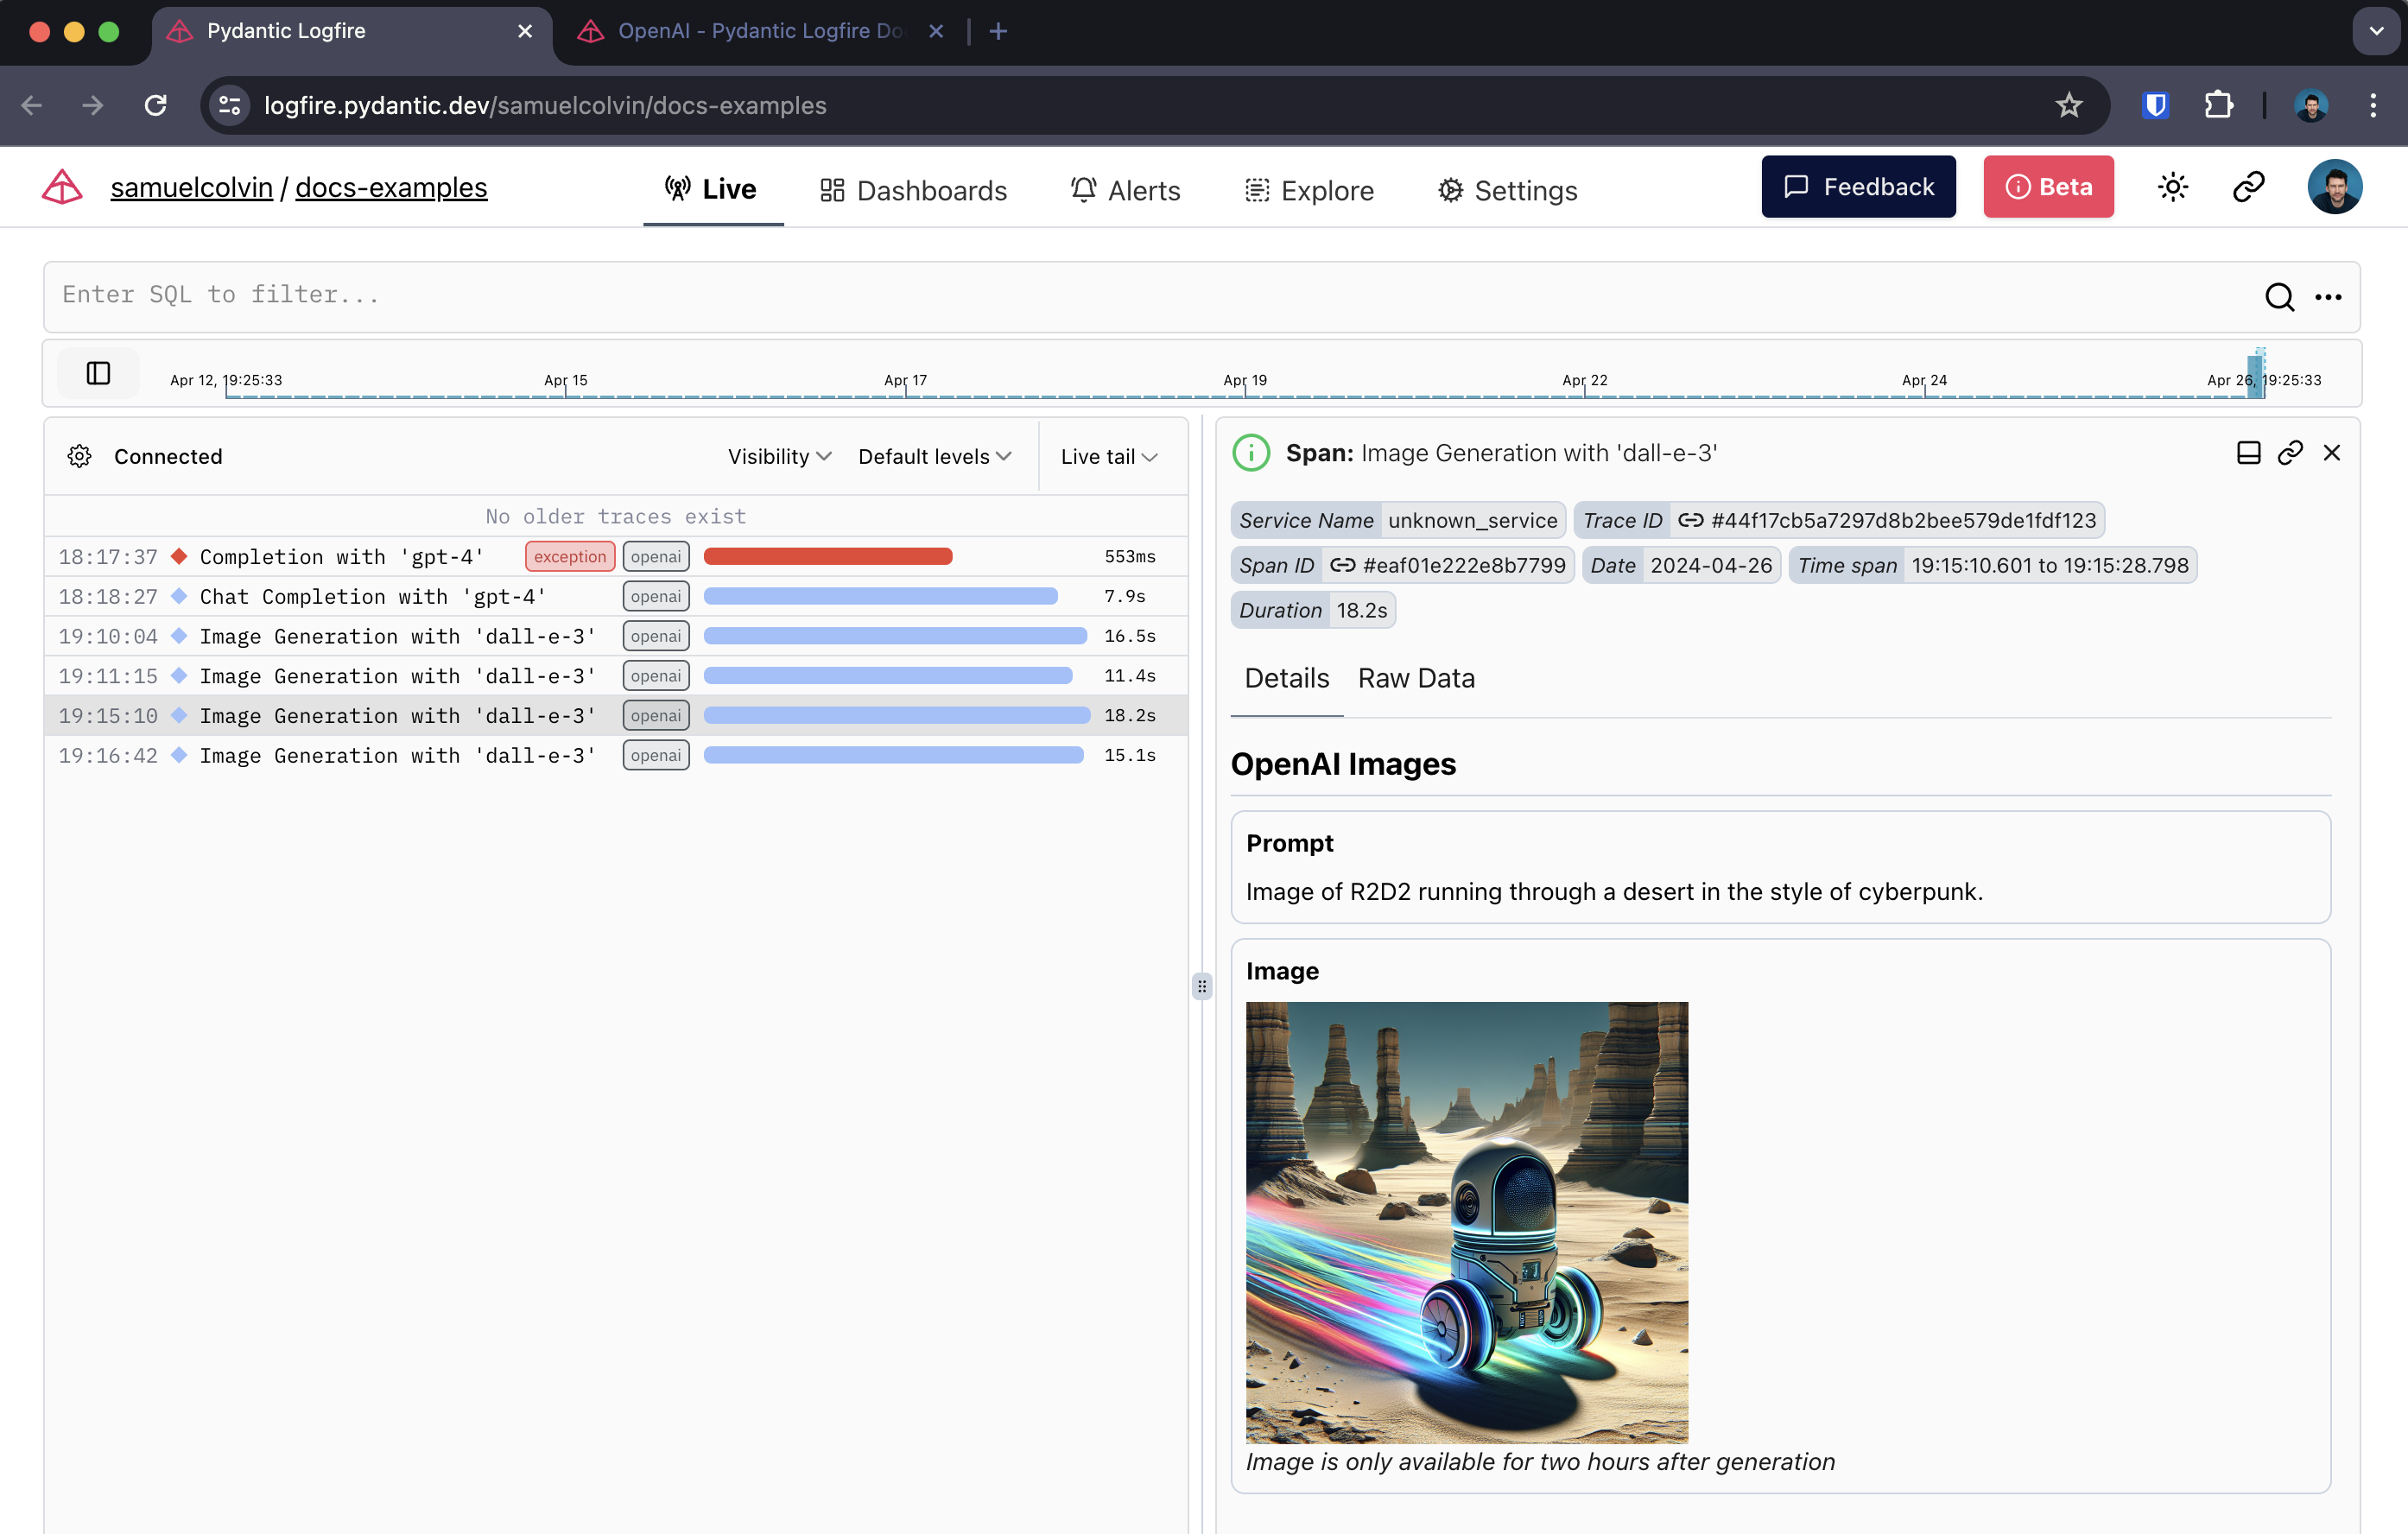
OpenAI 이미지 생성 범위
스트리밍 응답
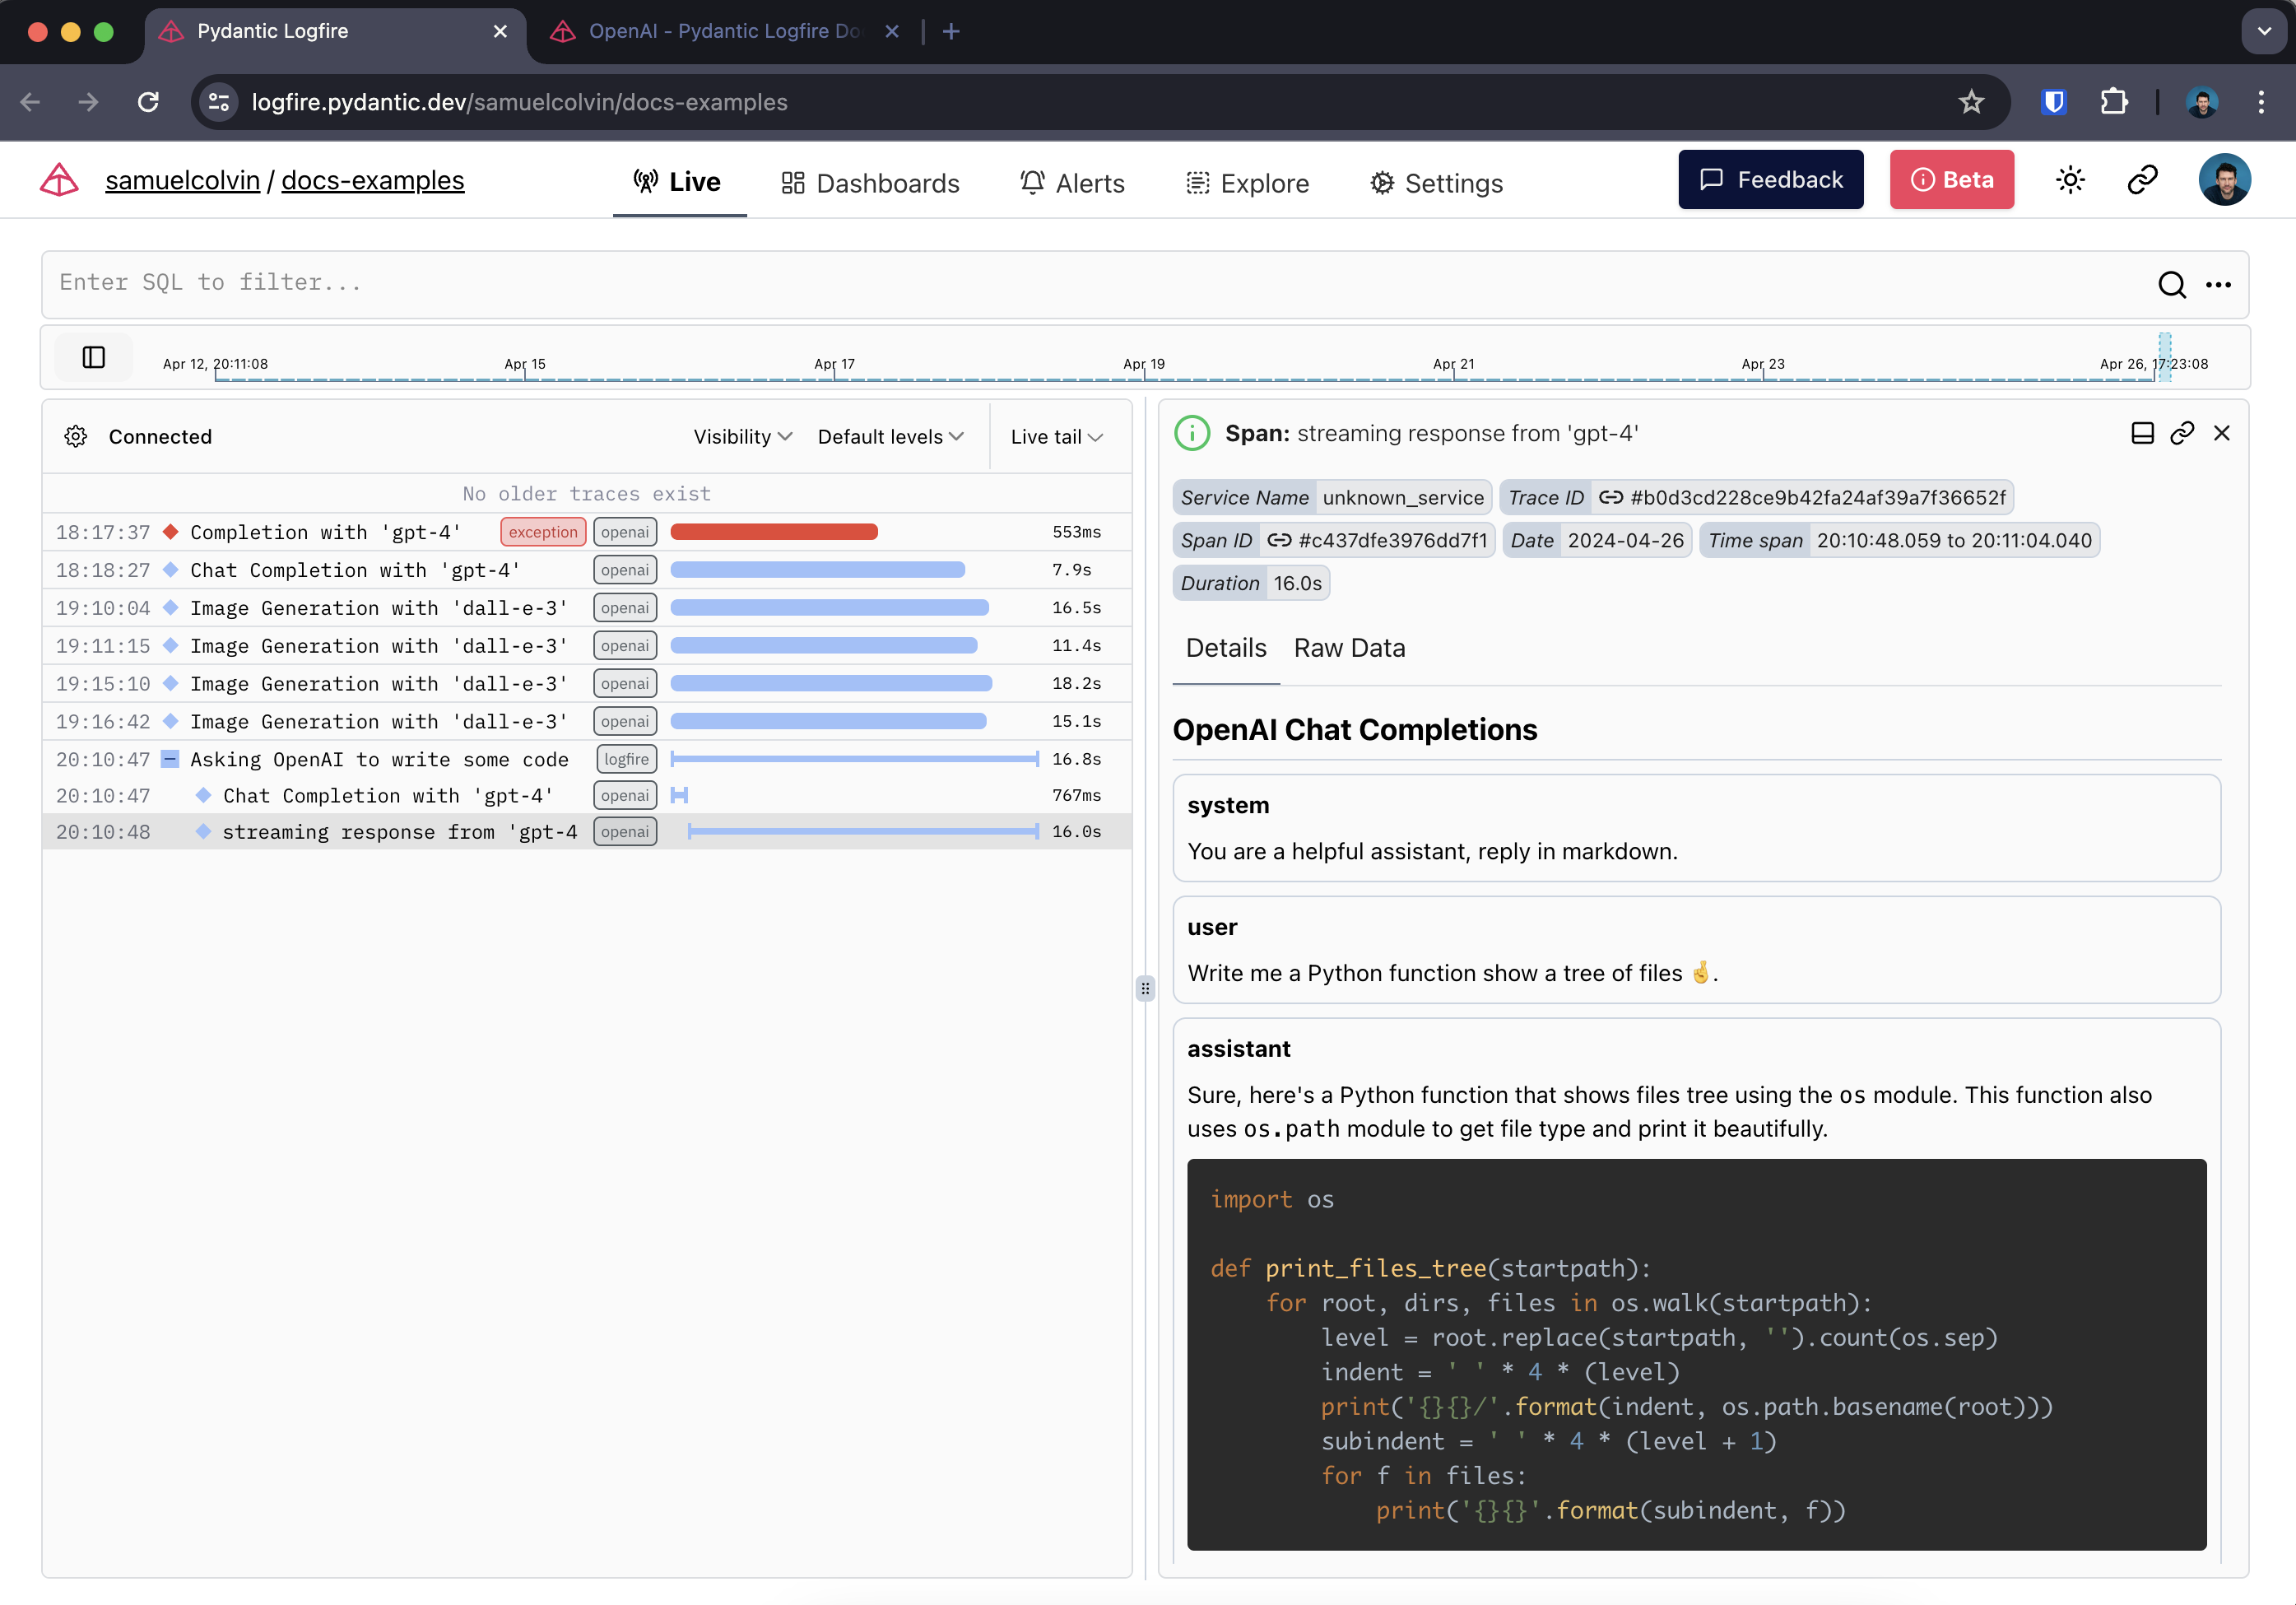
스트리밍 응답을 감지하면 Logfire는 두 개의 스팬을 생성합니다. 하나는 초기 요청 주위에, 다른 하나는 스트리밍 응답 주위에 있습니다.
여기에서는 Rich's도 사용합니다. Live 그리고 Markdown 유형은 종점에서 실시간으로 응답을 렌더링합니다.
import openai
import logfire
from rich.console import Console
from rich.live import Live
from rich.markdown import Markdown

client = openai.AsyncClient()
logfire.configure()
logfire.instrument_openai(client)

async def main():
    console = Console()
    with logfire.span('Asking OpenAI to write some code'):
        response = await client.chat.completions.create(
            model='gpt-4',
            messages=[
                {'role': 'system', 'content': 'Reply in markdown one.'},
                {'role': 'user', 'content': 'Write Python to show a tree of files 🤞.'},
            ],
            stream=True
        )
        content = ''
        with Live('', refresh_per_second=15, console=console) as live:
            async for chunk in response:
                if chunk.choices[0].delta.content is not None:
                    content += chunk.choices[0].delta.content
                    live.update(Markdown(content))

if __name__ == '__main__':
    import asyncio
    asyncio.run(main())
Logfire에서는 다음과 같습니다.
本文总阅读量次